This blog had been on Blogger since 2011. In November 2026 I moved it to Astro, with its content in Baack, the headless CMS I’m building. I wanted a site I own end to end, but I also wanted to run Baack’s onboarding on a real site with fifteen years of awkward content, not a demo, and see where it broke.
I did the work with Claude Code (Opus 5.5) and logged how long each step took. This is what happened, with the numbers.
At a glance
- Source: Blogger, with 75 posts and 7 pages from 2011 to 2026, 36 labels, and images left over from an older WordPress install.
- New site: Astro with React islands, Tailwind CSS and shadcn/ui, on Cloudflare.
- Blogger to Astro: 39m 52s from the first fetch of the old site to the first commit.
- Content in Baack: 88 entities and 1,184 items, including 122 images (27.6 MB).
- Writing it to Baack: under 2 minutes of API writes, across two runs.
- Pages changed by the move: none. All 122 pages show the same text as before.
Step 1: Blogger to Astro
The rebuild took one evening, 2 November. The first complete build came about 15 minutes after the first fetch of the live site:
| Step | Time |
|---|---|
| Audit the live site: sitemap, feeds, embeds and image hosts | 1m 01s |
| Scaffold Astro, React, Tailwind and shadcn/ui | 1m 42s |
| Write the Blogger importer and run it | 3m 41s |
| Switch to clean URLs with a redirect map, recover lost images and re-import | 1m 59s |
| Build the design, the templates, search and the image lightbox | 6m 38s |
The other 25 minutes went on testing in a browser, fixes, and changes I asked for along the way. Adding the Cloudflare config and testing all 120 redirects locally took another 2m 39s.
Old links still work. The importer writes a map from each Blogger path to its new clean URL, and Cloudflare serves those as 301 redirects.
Three things cost time:
- Dead images. Blogger’s feed still pointed at WordPress-era files that no longer exist. The Wayback Machine had 11 of the 18. The other 7 are gone.
- Blogger’s markup. Paragraphs made of
<br>s, code stored as inline code with literal backticks, a leftover WordPress[gallery]shortcode and Amazon tracking pixels each needed a rule in the importer. - Changing my mind. After the build had started I switched from keeping the old URLs to clean URLs with redirects, and from a serif design to sans. Both meant redoing work. Settle URL policy and typography before you build.
One early decision paid off later. A single module, src/lib/content.ts, is the only code that knows where content comes from. Reading from Baack meant changing it and the collection loaders. The templates only changed to mark what’s editable.
Step 2: onboarding into Baack
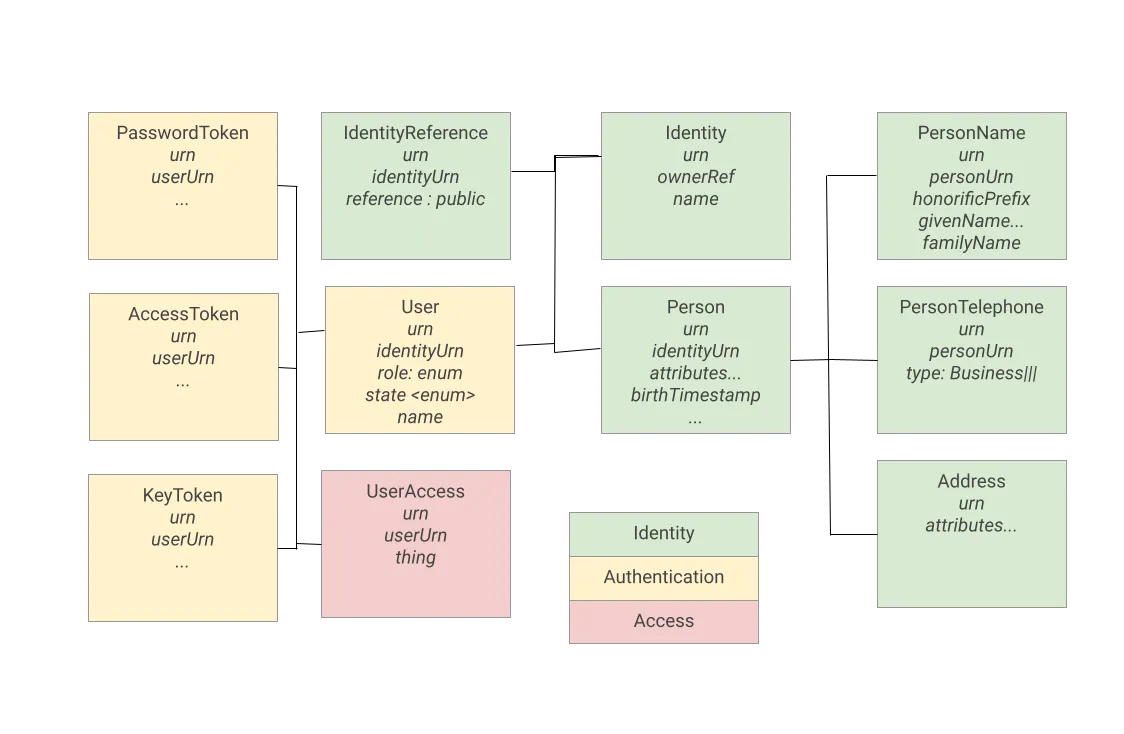
Baack stores a page’s content as an entity made of typed items: text, markdown, links, dates and images. Onboarding a site means finding every piece of content, deciding which entity it belongs to, tagging the templates so each piece is bound to its item, and then creating the items.
I used a draft of Baack’s content onboarding skill for Claude Code. It starts by recording what every page says, so it can prove later that nothing changed:
- Baseline: a build and the text of all 122 pages, in 23 seconds.
- Survey: 19 seconds. It found the header and footer on all 122 pages, 9 groups of pages sharing a template (posts and topics), and 289 pieces of copy repeated across pages.
- Scope: four questions for me. The answers: each post body stays one markdown item, and each image becomes an image item that the markdown links to.
The blog then found gaps that a simpler site wouldn’t have:
- Markdown bodies. Baack’s components showed an empty markdown item as its raw source in a single paragraph. Tagged as the skill described, all 82 post and page bodies would have broken until their items existed. Version 0.0.4 of the components fixes this:
ContentMarkdownandContentImagetake the page’s own rendering as children and show it until the item has a value. - The editor’s Create all. It starts a new markdown item from the element’s plain text, which would have flattened every body and dropped its formatting and images. The content was created by script from the Markdown source instead, and Create all now skips bodies that wrap the page’s own rendering.
- Images in bodies. Body images pointed at repository paths that only Astro can resolve. Each one is uploaded as an image item first, and the body’s Markdown points at its URL on Baack’s image host.
With every template tagged, the site passed all three checks: 122 of 122 pages with unchanged text, nothing in scope left untagged, and 32 views identical in layout to the baseline.
Writing the content
A sync script written for this site plans before it writes. The dry run listed 88 entities and 1,184 items to create (819 text, 82 markdown, 11 links, 150 dates and 122 images), 122 uploads totalling 27.6 MB, and no conflicting values.
The first real run, on 7 November, stopped after 54 seconds when the API closed a connection during an image upload. 44 entities had been written. Making reruns safe took about 3 minutes: the script now reads what it already created from its log, retries dropped connections, and finishes an image item left without its file. The second run wrote the rest in 50 seconds. Everything went in as drafts, and nothing was published.
Step 3: the first build from Baack
The first build that read Baack instead of the repository changed 91 of 122 pages. No content was lost, and every body matched its source length. But Baack’s entity view returns markdown already rendered as HTML, which skipped Astro’s pipeline:
- straight quotes and dashes instead of typographic ones
- no heading ids, so the table of contents linked nowhere
- no syntax highlighting in code blocks
- one image size instead of responsive images
The fix took about 11 minutes. A loader wrapped around Astro’s glob loader reads each body’s Markdown source from Baack and renders it with Astro, exactly as the repository’s files were rendered. After that, the Baack build and the repository build gave the same text on all 122 pages, with highlighting, heading ids and responsive images back.
If your framework already has a Markdown pipeline, read the source from the CMS, not its HTML.
Step 4: editing and deploying
Two more things came up before the editor was usable:
- The editor’s loader. The skill only sets up Baack’s in-page editor as part of Create all, so with content written by script that step was skipped. Adding the loader took about 21 minutes.
- Entity names. The posts were named after their URLs,
/writing/<post>, so in the editor the writing page looked like a folder of posts. I renamed them/blog/<post>and collected them in a/postsentity list, newest first. The site’s URLs didn’t change. The API wouldn’t rename the existing entities, so the script recreated them: 75 entities and 1,061 items, with the 122 images uploaded again. Decide your entity names before you write any content.
The site runs as a Cloudflare Worker serving the static build. A build that reads Baack takes 33 to 47 seconds, and a deploy about 20.
One trap is worth passing on. Cloudflare rebuilds the site on every push, and that build had no Baack token. Without a token the site fell back to the repository’s content, so the pages looked right but had no entity ids, and the editor had nothing to bind to. A missing token now fails the build instead. If your site has a fallback like that, make sure a production build can’t use it.
What changed in Baack
- Components 0.0.4.
ContentMarkdownandContentImagetake the page’s own rendering as children, with areplaceChildrenoption, and mark that markup withdata-markdown-wrapsordata-image-wraps. - The editor. Create all leaves wrapped markdown alone and says which items it skipped.
- The onboarding skill. This run found three gaps in it: it doesn’t set up the editor when content is created by script, it can’t exclude pages from its scope, and it doesn’t cover how a blog discovers new posts.
About the timings
These are elapsed times for Claude Code doing the work, not hours of human effort. They include the model’s thinking and the points where I changed my mind mid-build. Step boundaries come from file creation times and command output, not from memory.
The Baack phase ran from 5 to 9 November, with pauses and waits for my approval, so it has no meaningful total. The figures above are the spans measured as continuous work. A person doing the same work by hand would see different numbers.
What’s next
The repository still decides which posts exist, and this post is a Markdown file in it. The next step is reading the post list from Baack’s /posts entity list, so a new post needs no commit at all.